01
Language Representation
Underrepresented and low-resource languages receive uneven support from mainstream AI and OCR systems.
NASHIR
An AI-powered document intelligence and media archive platform focused on underrepresented languages, historical documents, and evidence-based access to information.
In development for over two years, built and tested through real-world work in Iraq, with a focus on challenging historical documents and underrepresented languages.
AI should not replace the source.
It should help people reach it.
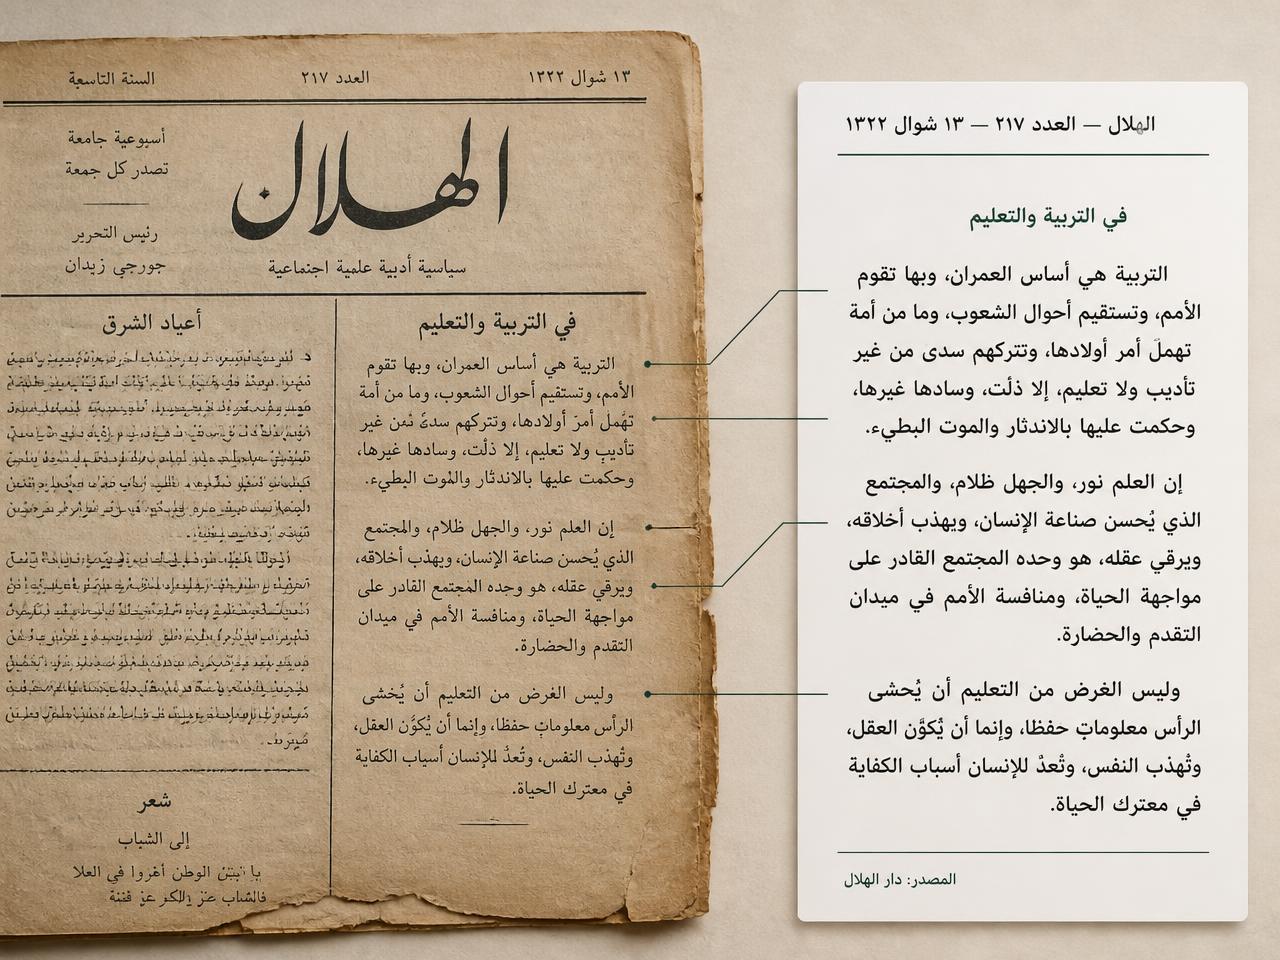
Figures below describe results on selected internal tests and the scope of the current collection. They are not universal benchmark claims.
400
pages processed in a single batch
5
languages tested
Up to 91%
on selected printed-document recognition tests
Up to 83%
on selected handwriting recognition tests
~150 years
of Iraqi press history
Thousands
of newspapers and publications
Live Demo
Al-Nasikh and the Iraqi Press Encyclopedia are working systems, not concepts. Reviewers can try both directly.
Access the live demo
Demo credentials are provided for reviewers. The account is read/demo-safe, has limited permissions, and contains no personal or confidential data.
The Problem
Digital transformation has not reached every language, script, and historical archive equally. Modern AI and OCR systems often perform best where large amounts of digital training data and commercial attention already exist.
Historical newspapers, scanned books, lithographic prints, degraded documents, and handwritten records introduce additional challenges.
For many communities, the problem is not that their history does not exist. The problem is that their history remains difficult for machines — and therefore difficult for modern search, analysis, and AI systems — to access.
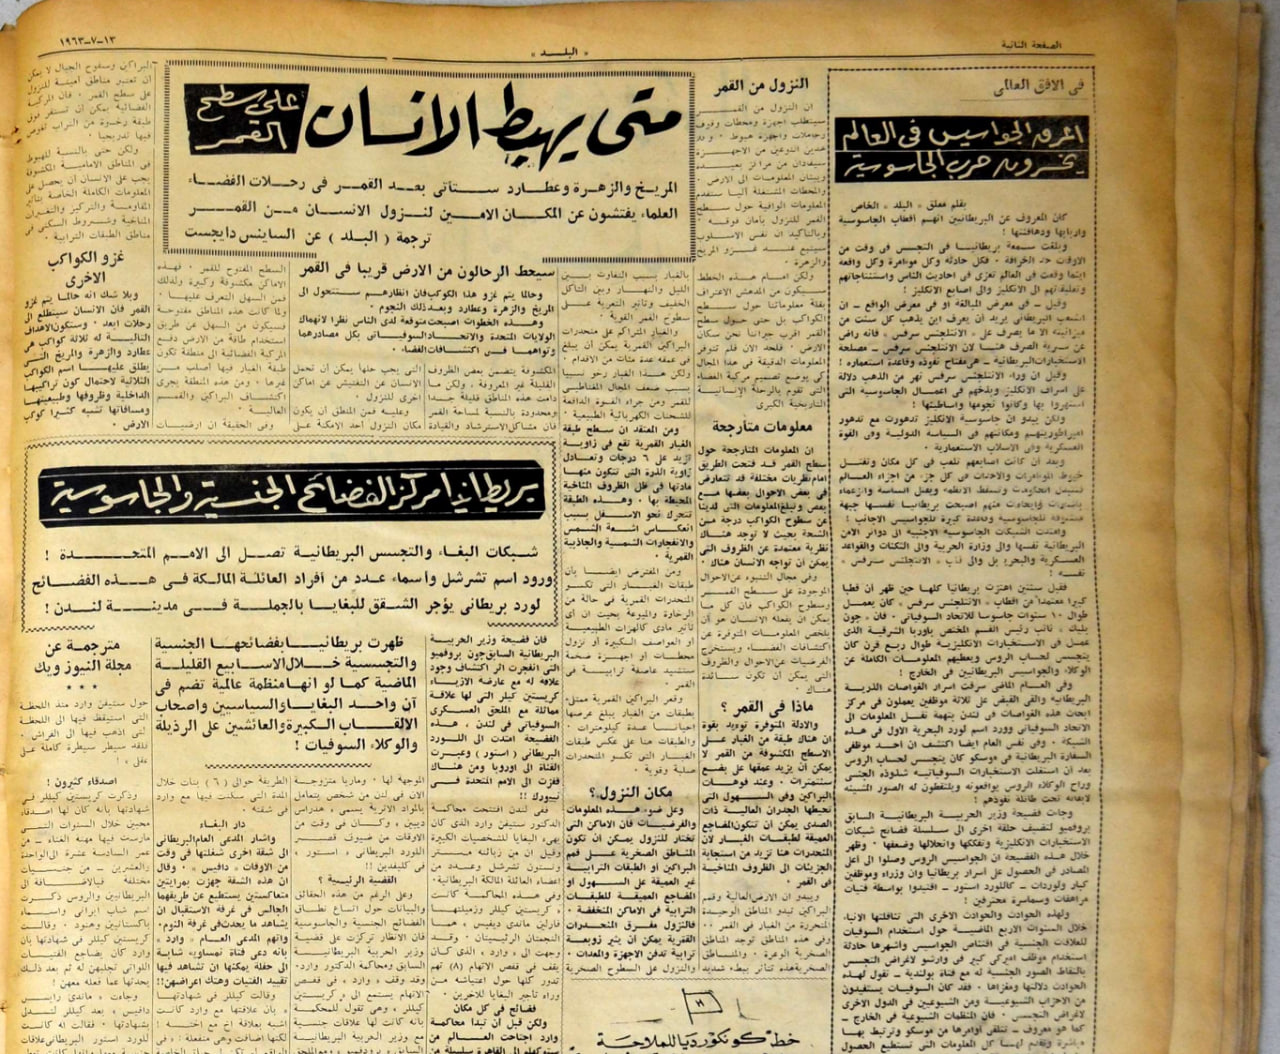
When historical information cannot be reliably digitized, entire communities face barriers to searching, studying, understanding, and verifying their own media history.
01
Underrepresented and low-resource languages receive uneven support from mainstream AI and OCR systems.
02
Historical printing methods, degraded pages, unusual layouts, and handwriting create additional recognition challenges.
03
Making information searchable is not enough. Users also need a way to return to the original source and verify what they see.
The Solution
Al-Nasikh provides the document intelligence layer. The Iraqi Press Encyclopedia demonstrates what becomes possible when historical media can be digitized, searched, explored, and connected back to its original evidence.
Layer 01 — Technology
AI-powered document intelligence for underrepresented languages and challenging historical documents.
Layer 02 — Real-World Application
A searchable digital implementation of a three-volume Iraqi press encyclopedia covering roughly 150 years of press history.
Layer 03 — Verification
Original pages, publication information, extracted text, and source context remain accessible to the user.
01Historical Documents
02Al-Nasikh
AI document recognition
03Digital Text
04Iraqi Press Encyclopedia
05AI-Assisted Discovery
06Original Source
07Verification
Technology Layer
AI document intelligence for languages and documents that are harder for mainstream systems to read.
Al-Nasikh is a working online platform developed to improve text extraction from underrepresented languages and challenging document types.
The platform is currently Arabic-first and has been tested across Arabic, Hindi, Hebrew, Swahili, and Javanese.
It is designed not only for modern printed documents, but also for historical printed material and Arabic handwriting.
Technical noteAl-Nasikh builds on open-source models and extends them through custom document-processing, preprocessing, recognition, and language-focused methods. The system is designed around the needs of underrepresented languages and challenging document collections.
Evidence from testing — selected test results
Up to 91%
Selected printed-document recognition tests
Up to 83%
Selected handwriting recognition tests
Results vary by document quality, script, layout, and test set.
Up to 400 pages in a single batch.
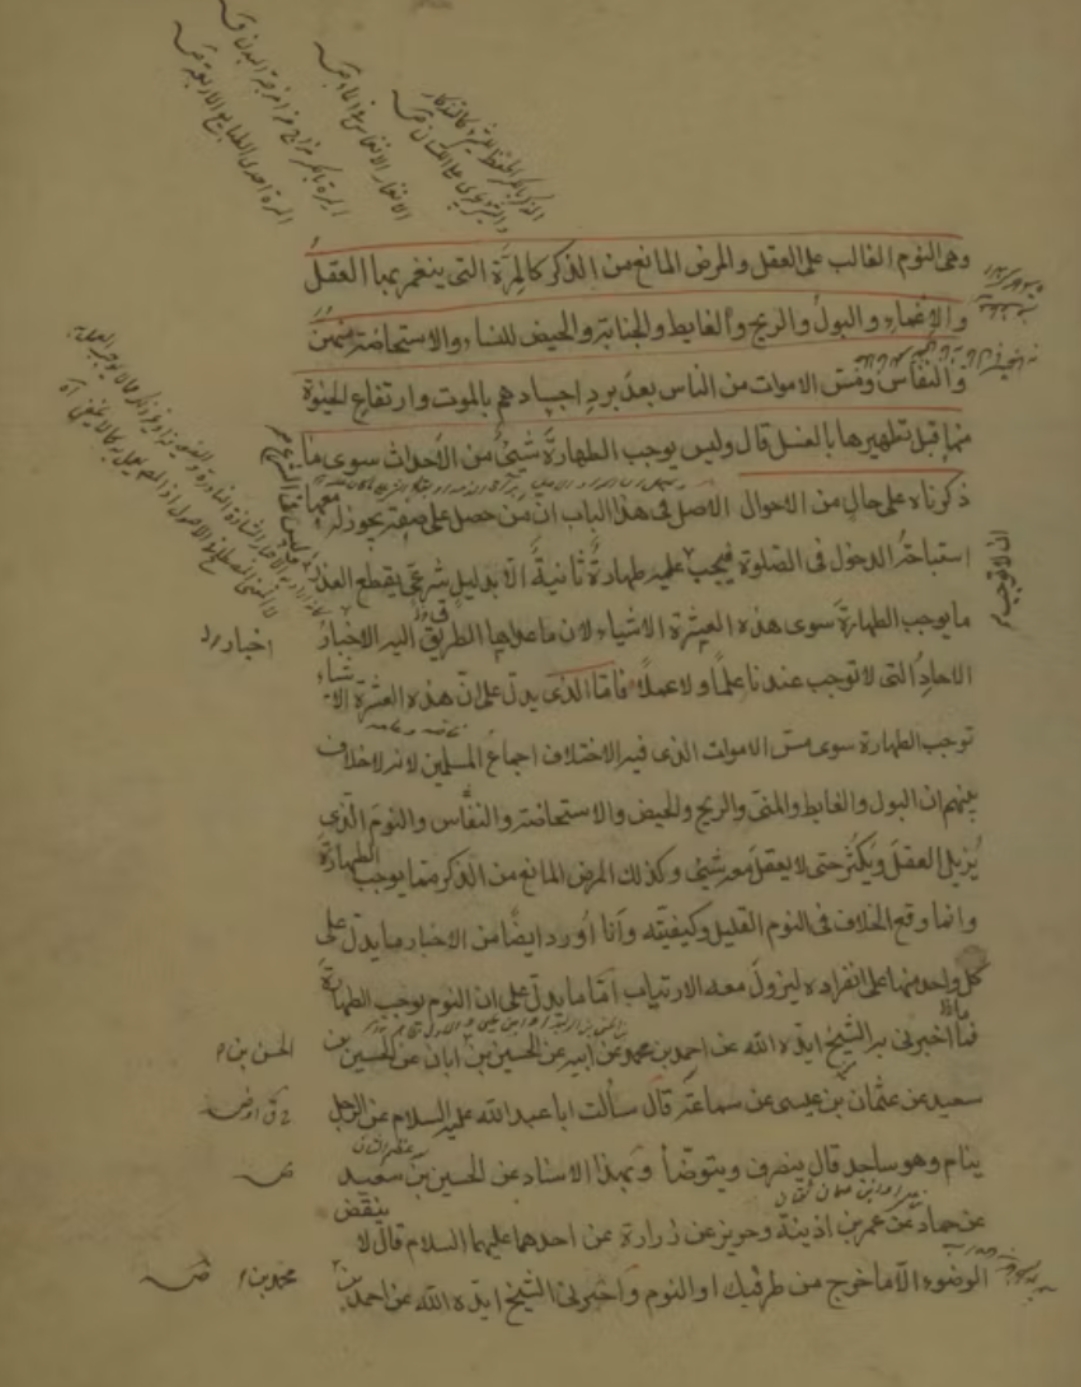
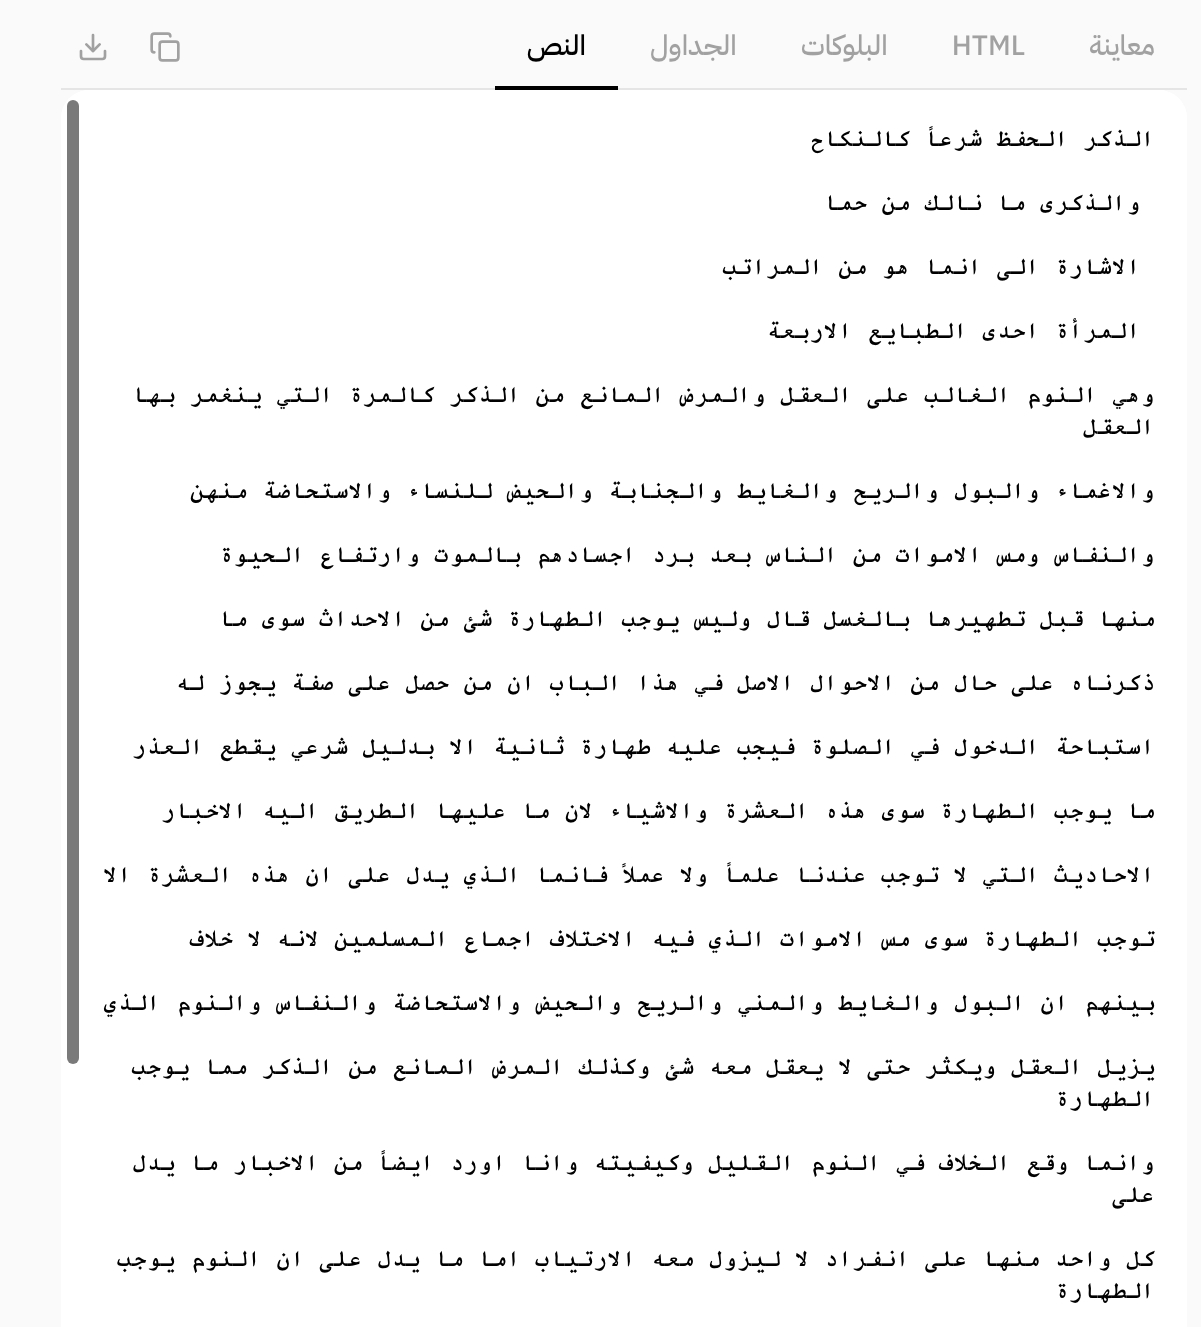
Tested on good-quality handwritten Arabic documents.
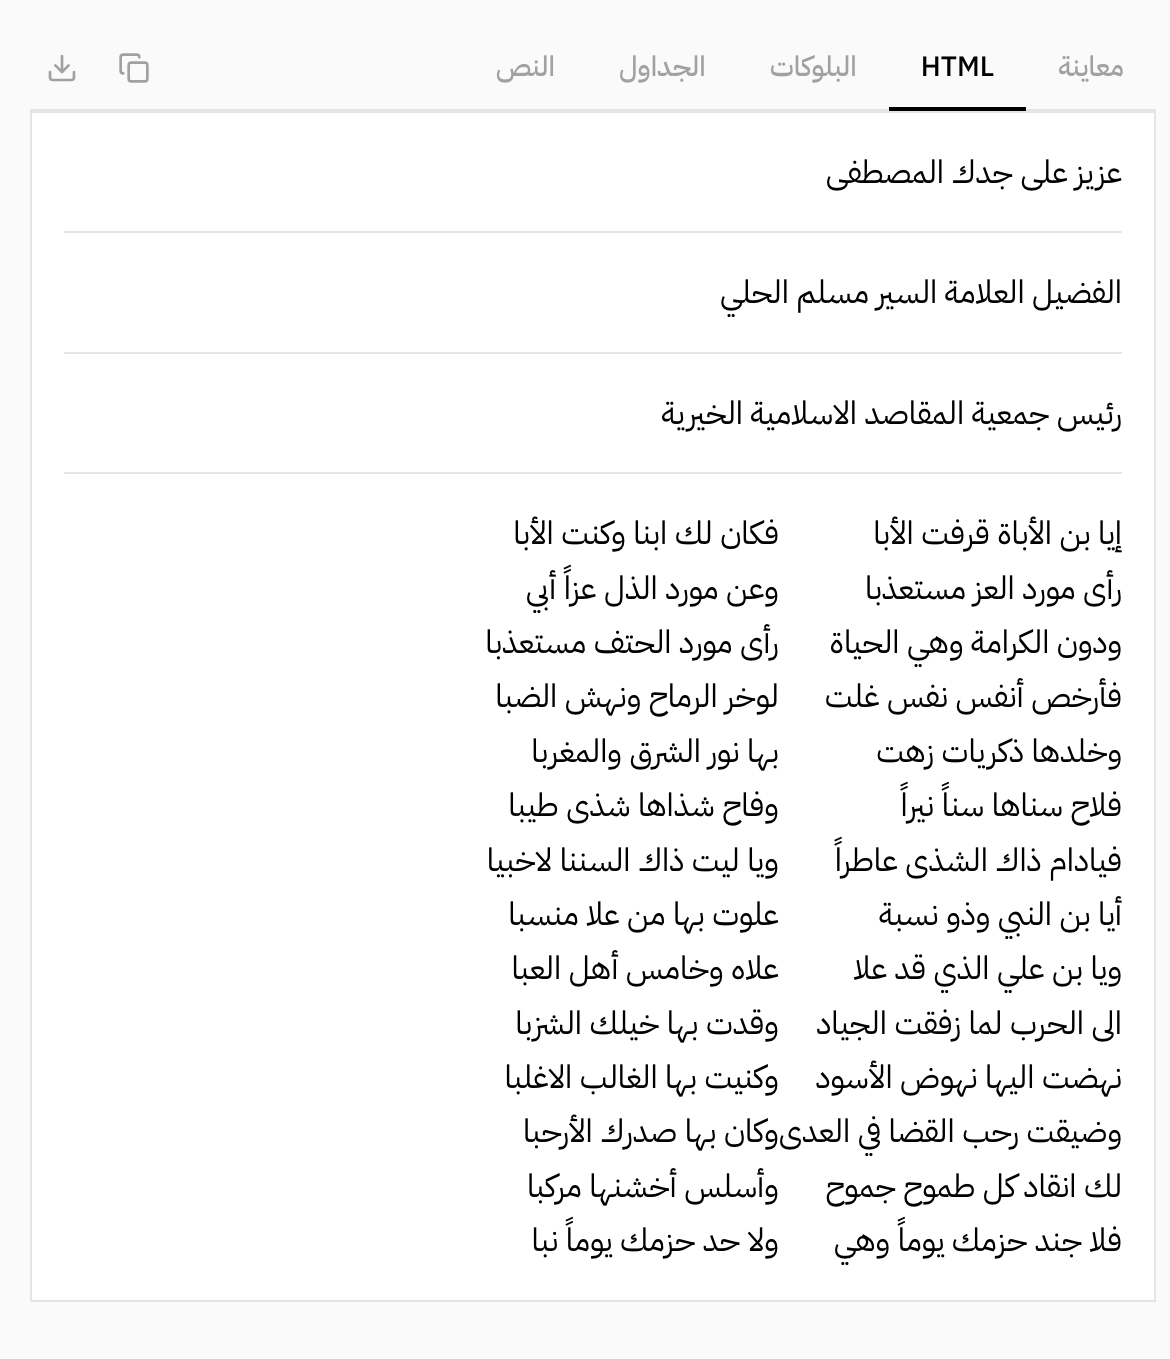
Tested on historical printed and lithographic documents.
Tested on selected good-quality handwritten Arabic documents.
Languages Tested
Example 1 — Historical Printed Document
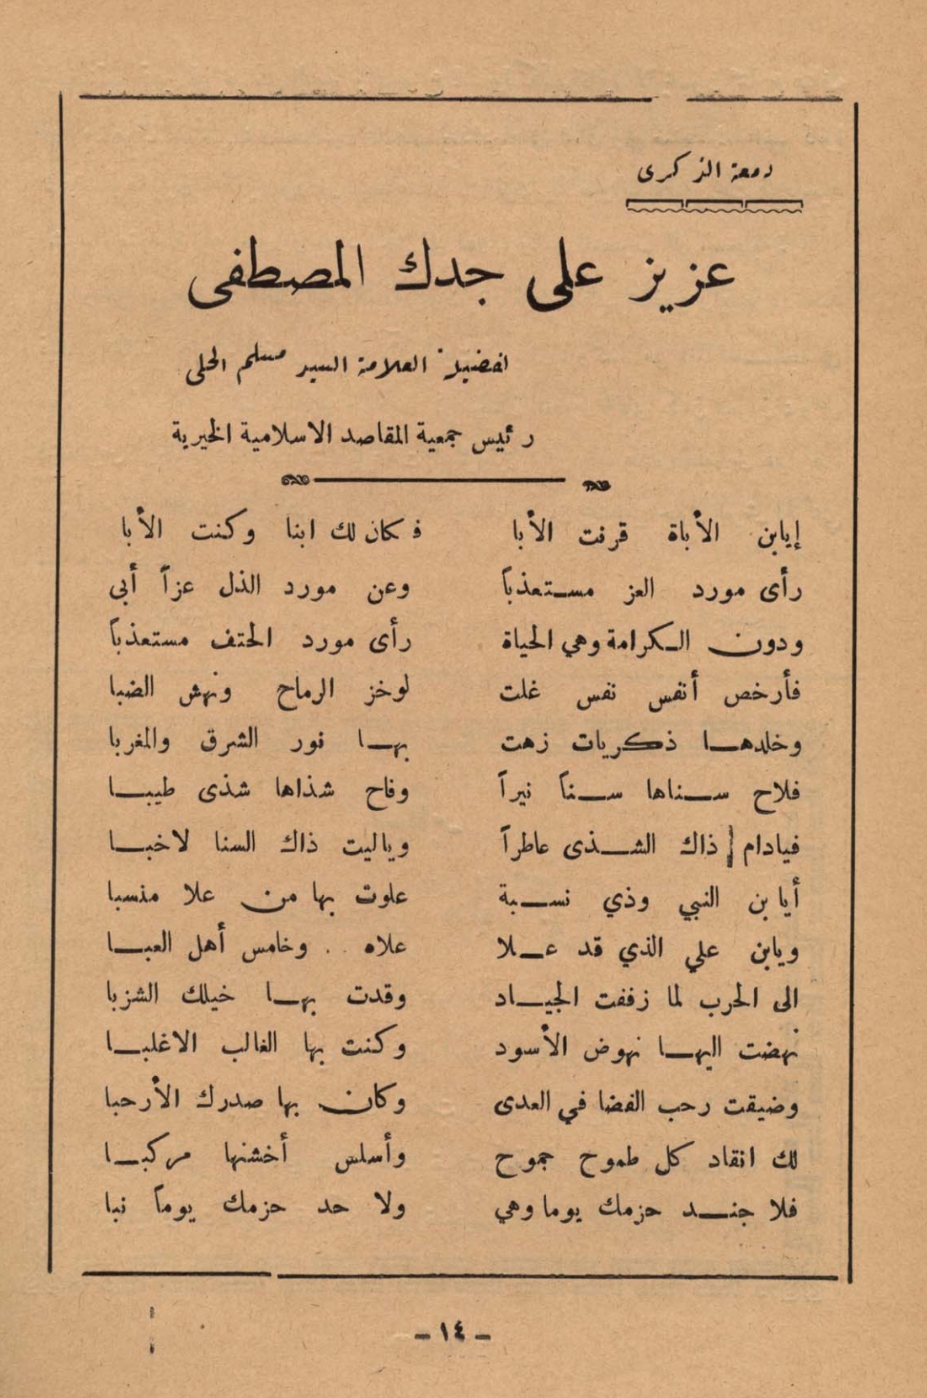
Example 2 — Arabic Handwriting
Real-World Application
A real-world application of the technology.
An original three-volume encyclopedia documenting Iraq's press history has been transformed into a searchable digital knowledge platform.
The collection covers roughly 150 years of Iraqi press history and includes thousands of newspapers and publications.
Search across digitized press content using words and text.
Explore publications by publication date and historical period.
Filter and explore different types of publications.
Explore the collection through available classifications.
Explore information associated with people and other entities where available.
Open the original encyclopedia/document page as an image.
Use AI to help explore and understand the collection while maintaining a connection to source material.
Search to Source
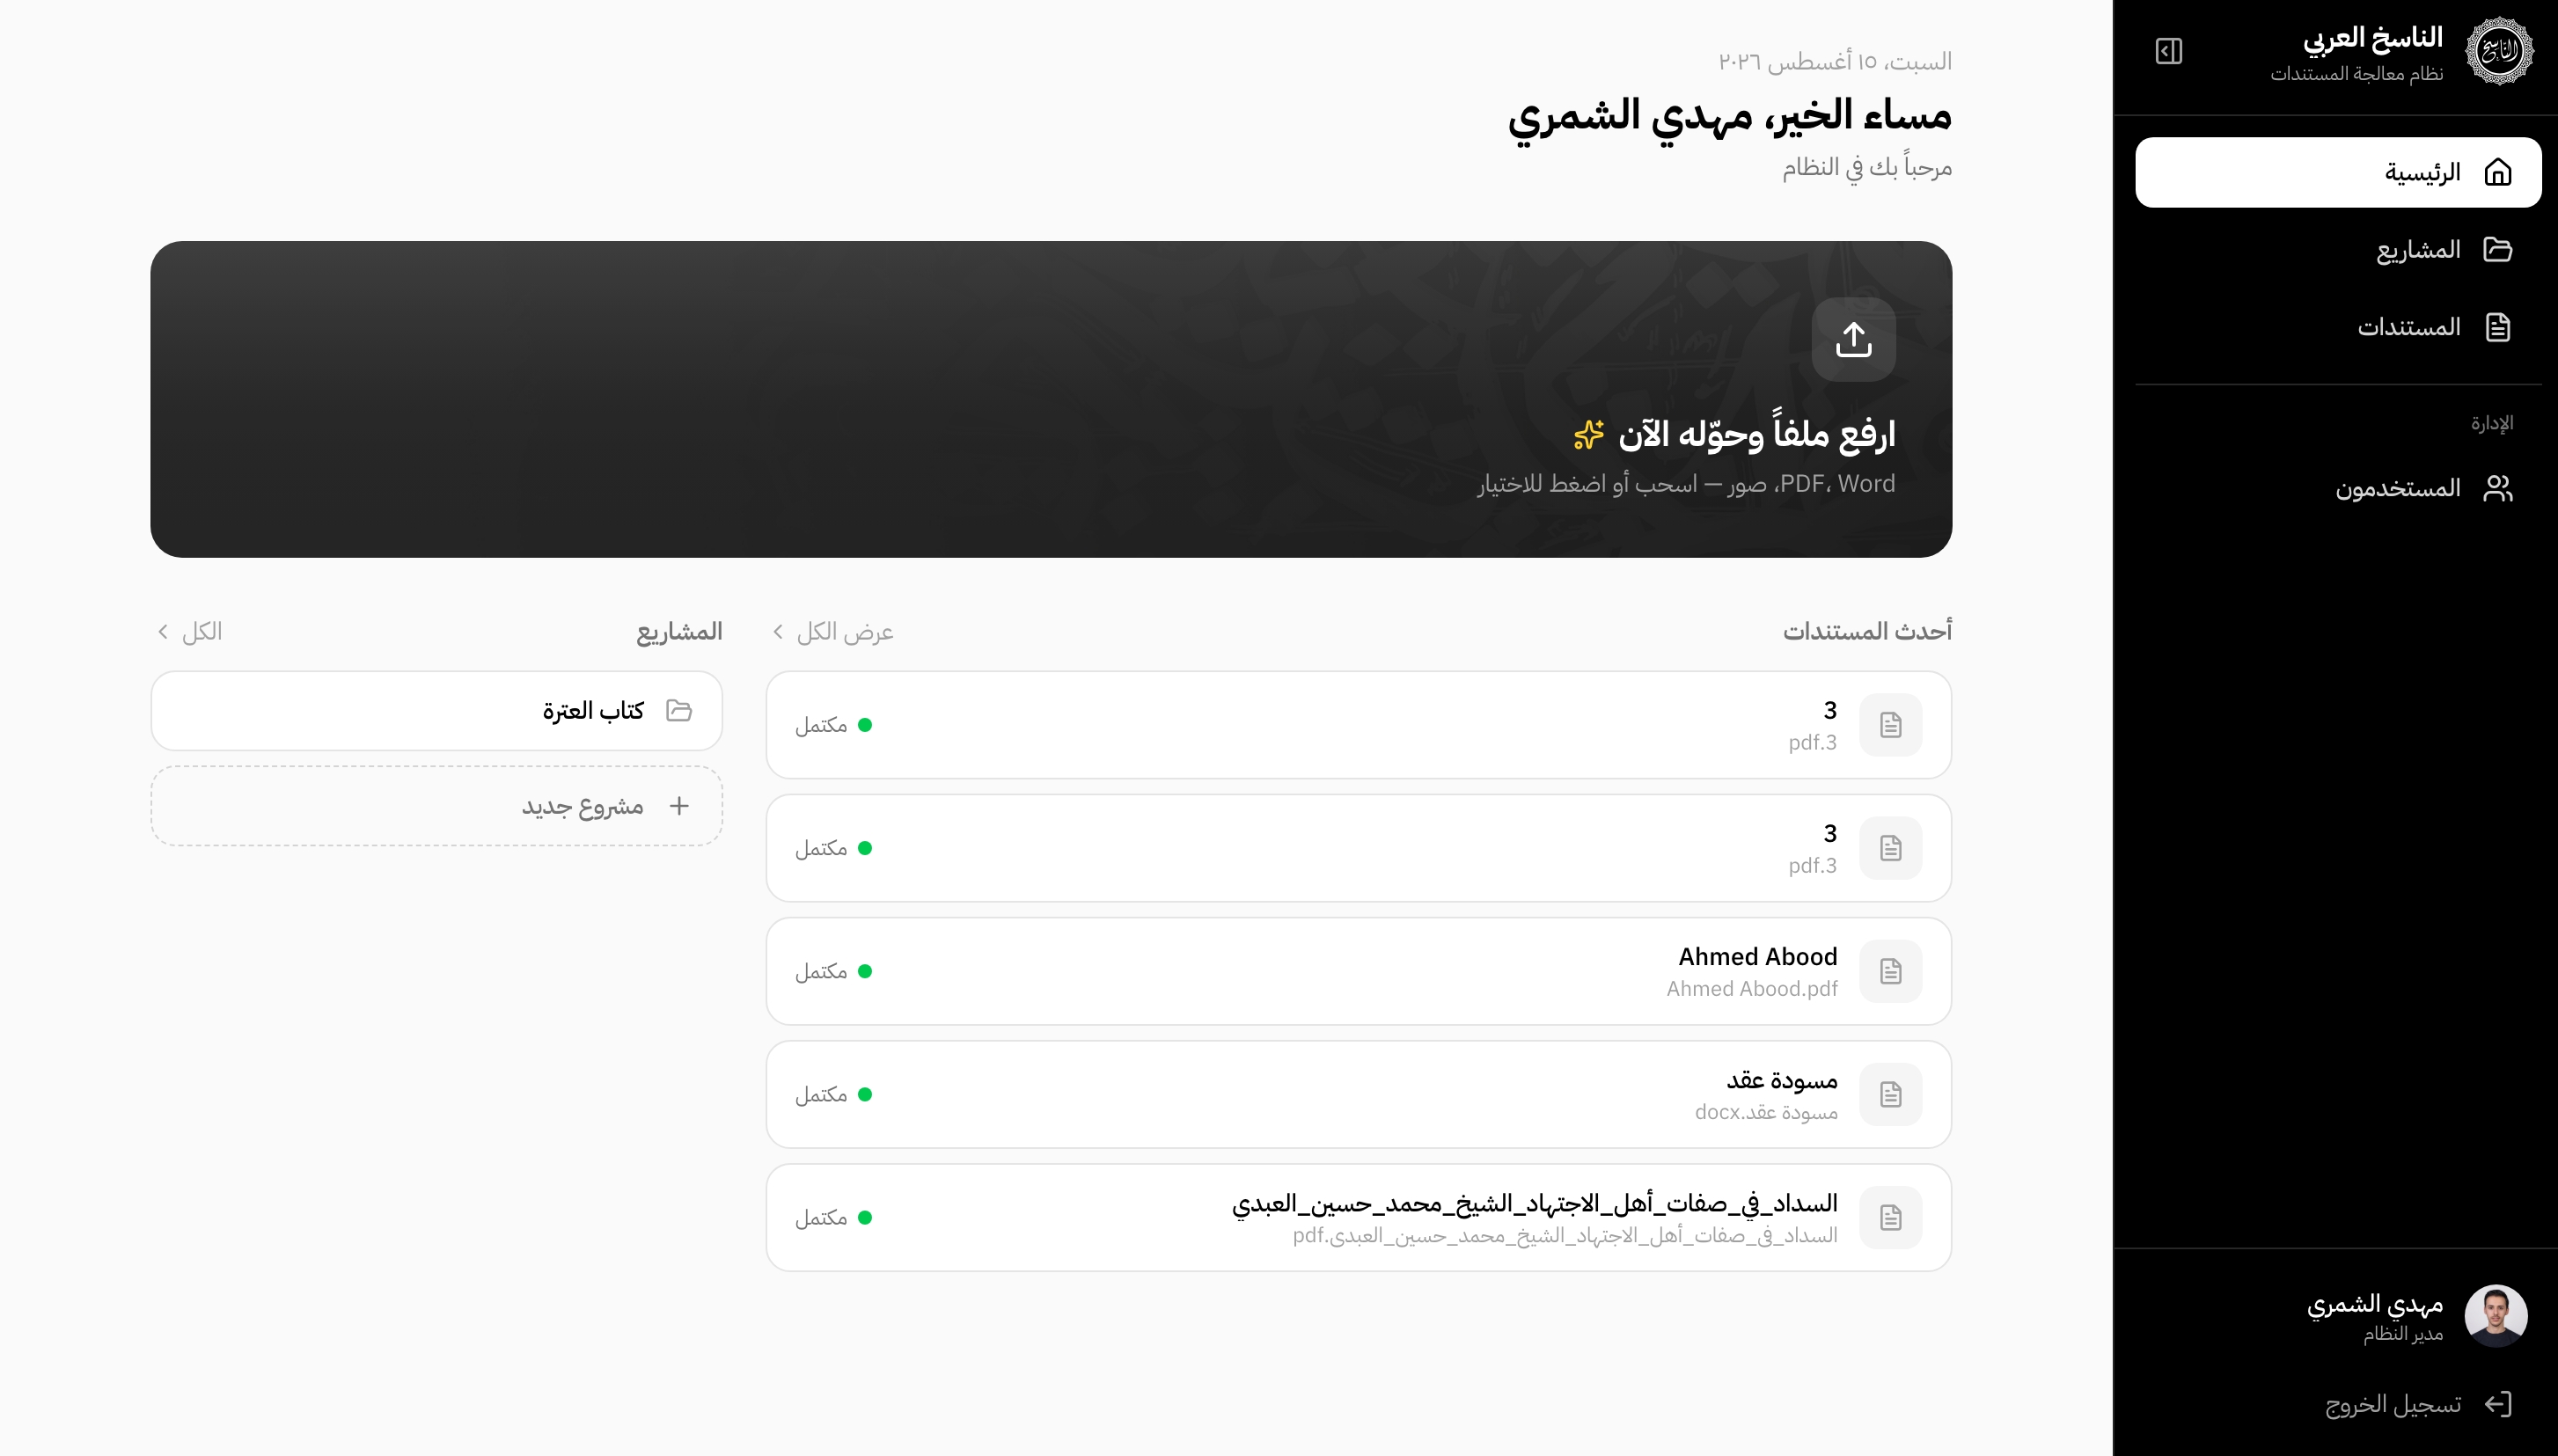
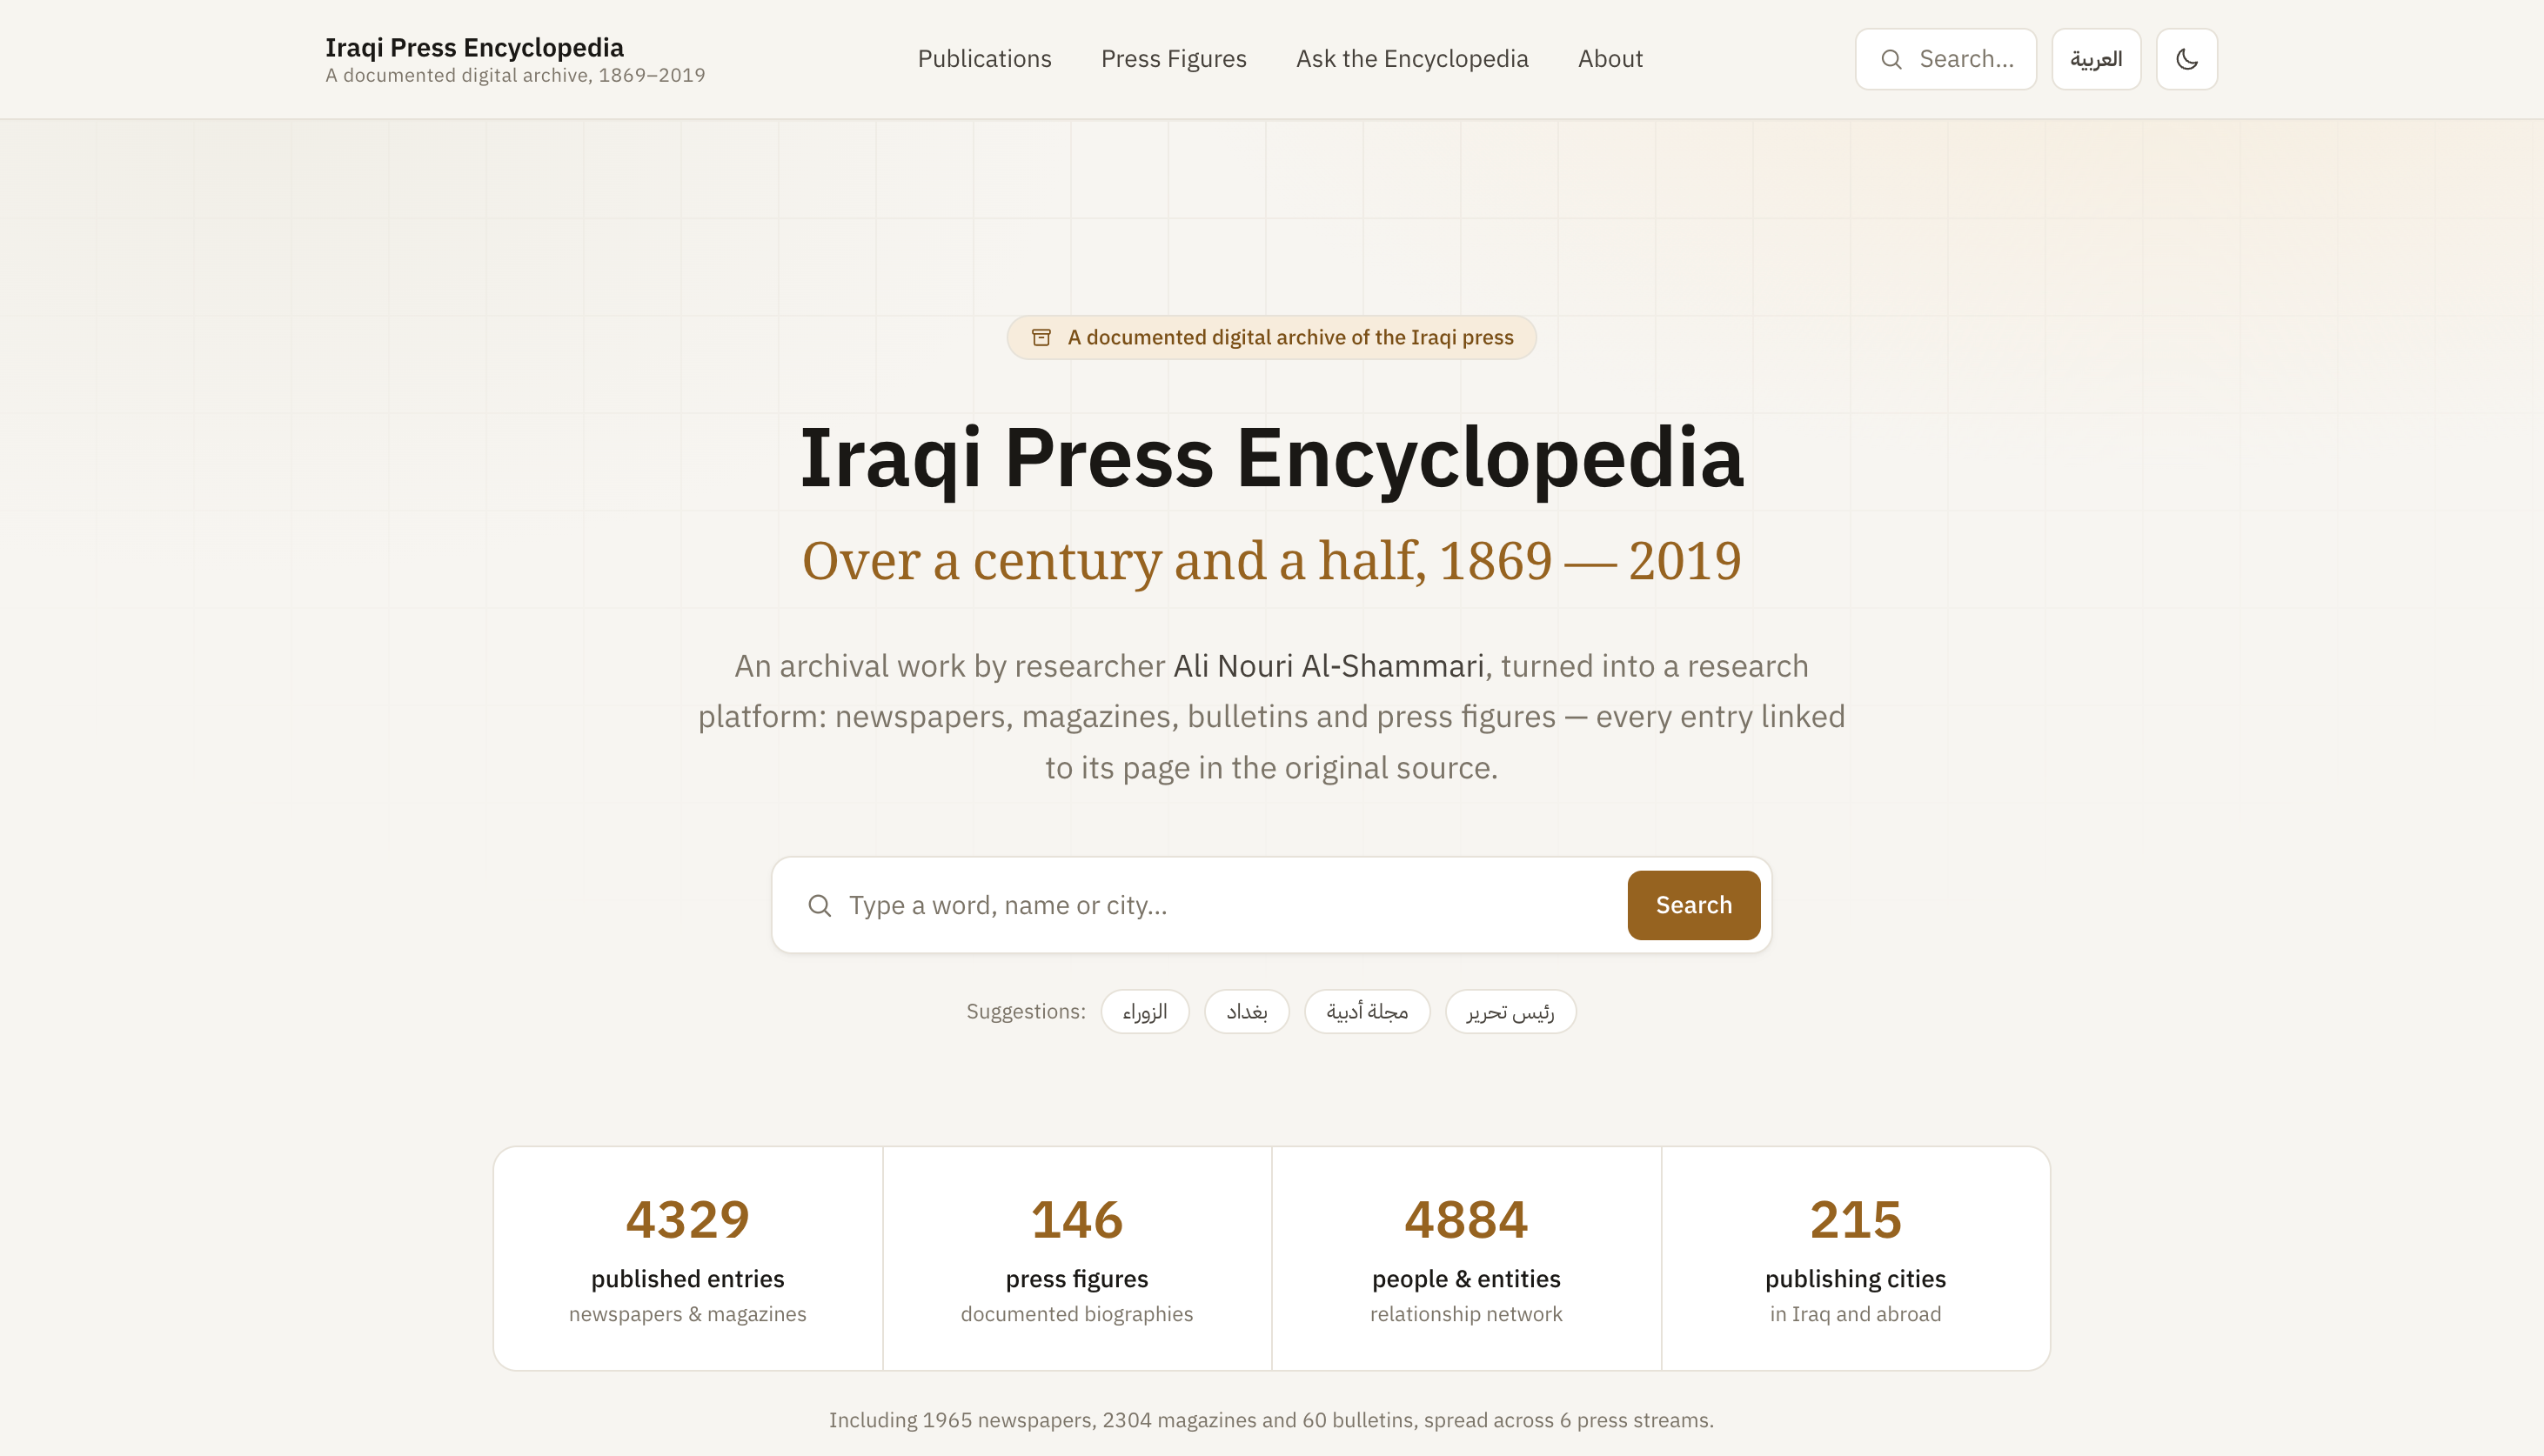
A real search in the Iraqi Press Encyclopedia stays connected to its original page at every step.
01User Question
02AI-Assisted Search
03Result
04Publication, Date, Page
05Original Page Image
06Extracted Text
07Verification
Illustrative view of the encyclopedia's homepage alongside an archival source page. Explore the live platform for a complete search-to-source walkthrough.
Evidence
We do not want users to simply trust an AI-generated answer. We want AI to help them reach the evidence.
Every useful result should remain connected to the material from which it was derived.
Instead of presenting information as an isolated AI response, the platform can lead users back to the original page, publication, date, and extracted text.
Evidence Panel
01Question
02AI-Assisted Search
03Result
04Source
05Original Page
06Verification
AI → Answer → Evidence → Verification
Media & Information Literacy
Media and Information Literacy is not only about accessing information. It is also about understanding where information comes from, evaluating it critically, and making informed judgments about what to trust and share.
Our approach uses AI as an access and discovery layer while preserving the user's ability to inspect the underlying evidence.
The MIL layer is not an additional feature. It is built into how information is presented: search → context → source → verification.
Discover information that was previously difficult to search.
Use AI-assisted tools to explore large historical collections.
Examine context, metadata, sources, and uncertainty.
Return to the original document before accepting or sharing information.
AI should expand access to evidence — not replace evidence.
Impact
The project connects technical innovation with a public information need: making historical media more accessible without losing the connection to the original record.
01
Access historical reporting and primary media sources that are difficult to search digitally.
02
Search and analyze historical media collections at a scale that would be difficult through physical archives alone.
03
Develop stronger habits of source-based research and critical engagement with information.
04
Help bring languages and documents with limited AI representation into the digital information ecosystem.
05
Help cultural and media archives become more accessible, searchable, and useful to researchers and communities.
Iraq is the starting point — not the boundary.
The same approach can be adapted to other historical newspaper collections, cultural archives, and underrepresented languages around the world.
Potential future applications — not yet supported
Approach
Future Direction
Our long-term vision is to help cultural and media archives become machine-readable, searchable, and accessible while preserving the connection to their original sources.
Starting with Iraq, the technology can evolve toward broader support for underrepresented languages, historical publications, and community archives.
Expand support for additional underrepresented and low-resource languages.
Apply the workflow to historical newspapers and cultural collections.
Strengthen source linking, provenance, and evidence-aware AI interactions.
These directions describe planned work. They are not presented as completed capabilities.
Project Status
Research
Completed
Prototype
Completed
Working Platform
Completed
Real-World Application
Completed
Scaling & Expansion
In progress
Al-Nasikh is already available as a working online platform.
The Iraqi Press Encyclopedia is an active digital implementation demonstrating how the technology can be applied to a large historical media collection.
The next stage is to expand the technology, improve language coverage, and make the approach applicable to more archives and communities.
Project Origin
This project grew from a practical challenge: how can historical Arabic and other underrepresented-language documents become accessible to modern digital systems without losing the evidence contained in the original documents?
The work has been under development for over two years, combining software engineering, document processing, OCR experimentation, digital archiving, and AI-assisted information retrieval.
Project Lead
Software engineer leading the design and development of Al-Nasikh and the Iraqi Press Encyclopedia.
Assistant
Software developer supporting the project's development and testing.
Archive & Product Development
Works on archive development and product direction for the Iraqi Press Encyclopedia.
UNESCO Youth Hackathon 2026
NASHIR has been in development for over two years. In 2026, the project is taking part in the UNESCO Youth Hackathon 2026, at the intersection of Artificial Intelligence and Media and Information Literacy.
Call to Action
The technologies that shape our information environment should not leave languages, communities, or historical records behind.
Al-Nasikh begins with document access. The Iraqi Press Encyclopedia demonstrates what becomes possible. The larger goal is a more inclusive and verifiable information ecosystem.